
 AReno
AReno documentation#
Local post-training and serving
Train and serve local LLMs with one native loop.
AReno keeps rollout, reward scoring, inference, optimizer steps, and checkpoint I/O in one compact engine for SFT, DPO, GSPO, GRPO, PPO, and agentic RL workflows.
Start#
Install
Install the native runtime.
# Linux / CUDA
bash scripts/install.sh
# Apple Silicon / MLX
python -m pip install -e .
Use the CUDA installer on Linux or the native MLX pip path on Apple Silicon.
Check
Verify the local runtime before training.
areno check
areno env --json
Confirm CUDA readiness on Linux or the selected MLX backend on Apple Silicon before loading a checkpoint.
AReno selects CUDA on Linux and MLX on Apple Silicon. The CUDA installer also selects the attention setup, preparing FlashAttention for supported GPUs and leaving older GPUs on AReno’s native compatibility backend.
Core workflows#
Run SFT, DPO, GSPO, GRPO, or PPO from the CLI with dataset loading, rollout, reward scoring, and checkpoint saving in one loop.
ServeStart an OpenAI-compatible chat-completions server backed by the local AReno inference engine.
CustomizeUse from areno import Trainer for custom rollout, reward, loss, and checkpoint loops.
Review the checkpoint families currently supported by AReno model adapters.
Training
Run a small GSPO smoke task.
areno train \
  --ckpt Qwen/Qwen3-0.6B \
  --dataset-path gsm8k:main \
  --dataset-loader-fn examples/math/dataset_loader.py \
  --reward-fn-path examples/math/math_verify_reward.py \
  --algo gspo \
  --tp-size 1 \
  --world-size 1 \
  --batch-size 1
Serving
Open a local chat-completions endpoint.
areno serve \
  --model-path /path/to/model \
  --tp-size 1 \
  --world-size 1 \
  --port 8000
Training and serving require a CUDA-capable NVIDIA GPU on Linux or Apple Silicon with MLX. Other CPU-only machines can run docs, packaging checks, and lightweight tests, but cannot run an AReno training or serving backend. See mlx for the Apple Silicon path.
Agentic rollout#
Agentic RL
Collect trajectories through a local OpenAI-compatible proxy.
Agent functions call the local server, return explicit trajectory turns, and let AReno convert responses into completions, tokens, logprobs, rewards, and loss masks.
areno train \
  --agent-fn examples/agentic/tictactoe/run_agent.py \
  --reward-fn-path examples/agentic/tictactoe/reward.py \
  --algo gspo
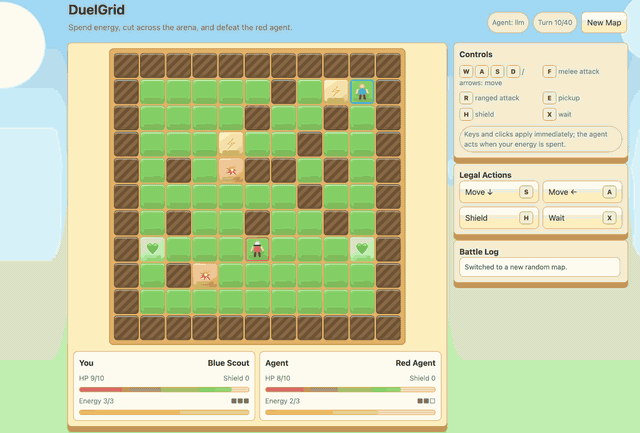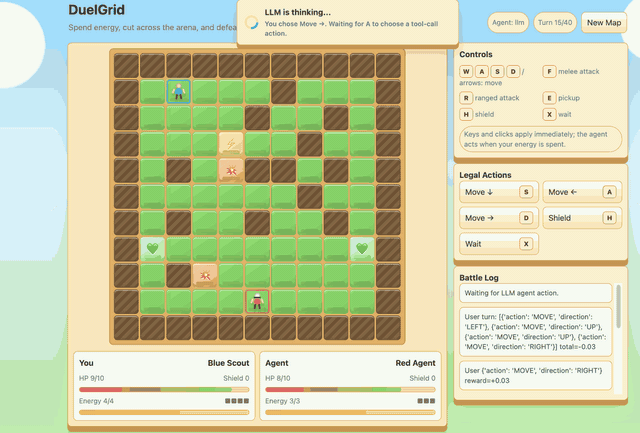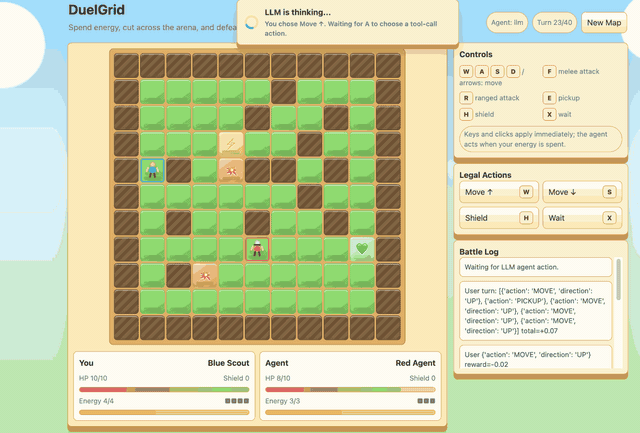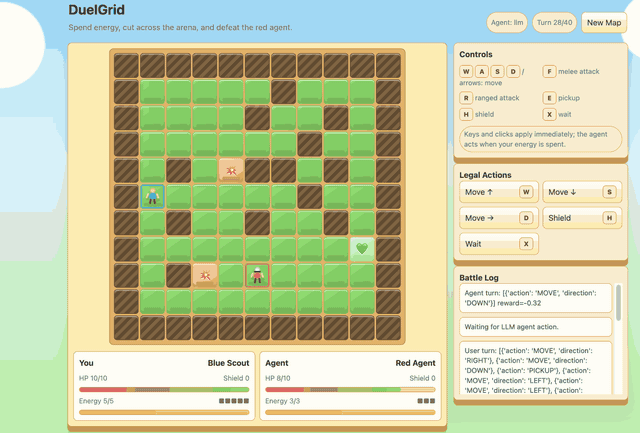
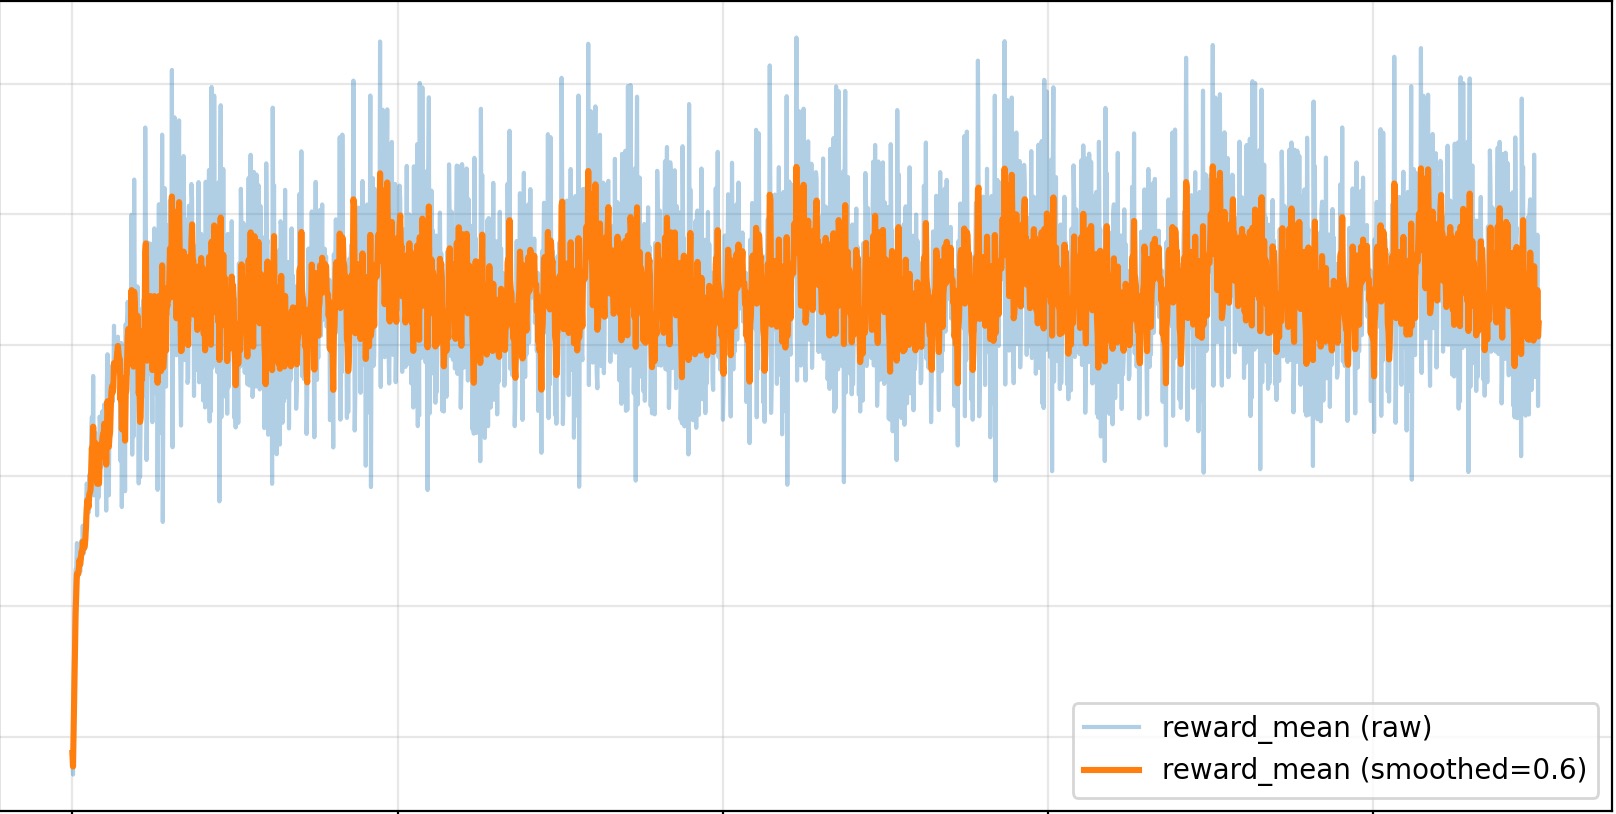
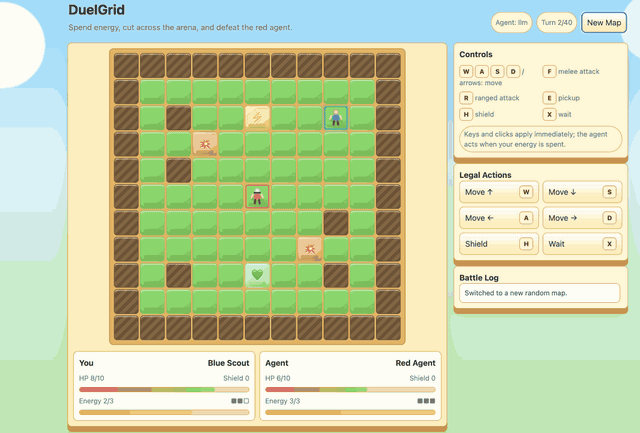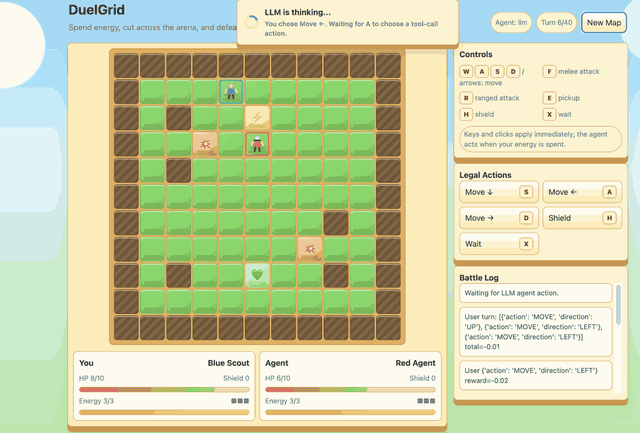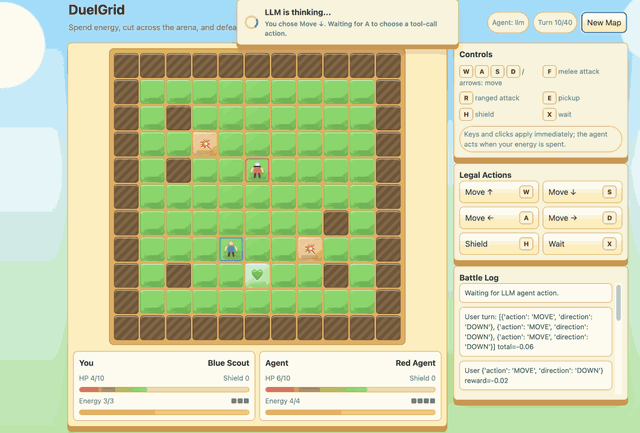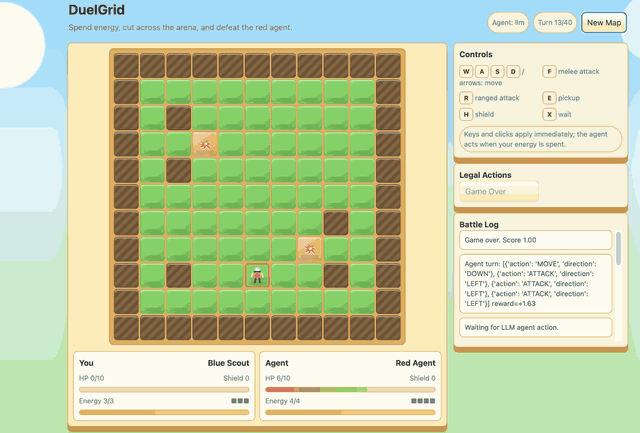
DuelGrid is a browser-game demo with multi-action turns. Before GSPO/RLVR post-training, Gemma-E2B-it often moves back and forth without progress. After training, it learns to collect pickups, chase the user, attack when in range, and avoid trap tiles.
Train before |
Reward |
Train after |
|---|---|---|
|
|
|
See examples/agentic/duelgrid for the rule engine, fixed-path dataset
loader, reward function, OpenAI-compatible agent, and browser UI.
What AReno owns#
Fused areno_accel CUDA paths on Linux and native MLX execution on Apple Silicon.
Backend-native KV/cache layout, rollout state, scoring, optimizer steps, continuous batching, and checkpoint I/O.
SFT, DPO, GSPO, GRPO, PPO, and agentic rollouts implemented inside the project rather than delegated to a separate trainer framework.
Hugging Face-oriented CUDA checkpoints and native MLX checkpoints with tokenizer and processor assets.